OpenAI’s 10,000 AI Agents and the Navier–Stokes Breakthrough: What It Means for AI Research
Artificial intelligence is entering a new phase of scientific research. Instead of asking a single AI model to solve a problem and waiting for an answer, researchers are beginning to build systems in which thousands of AI agents can explore different approaches simultaneously, exchange information, write code, test ideas, and gradually converge on promising solutions.
OpenAI’s recent work on the Navier–Stokes problem offers one of the clearest demonstrations yet of this approach. The company says an internal AI system, supported by a large network of coordinating agents, produced a proposed solution to one of mathematics’ famous Millennium Prize Problems. The effort involved around 10,000 concurrent agents, millions of internal messages, and billions of generated tokens.
The mathematical result itself still requires careful independent scrutiny. But even before the mathematical debate is settled, the experiment raises a larger question that could matter far beyond mathematics:
What happens when AI research stops being a single-model conversation and becomes a coordinated research process involving thousands of specialized agents?
That may ultimately be the more important story.
What Happened With the Navier–Stokes Problem?
The Navier–Stokes equations describe the behavior of fluids such as water and air. They are fundamental to fields ranging from fluid dynamics and engineering to weather and physical science.
One of the major mathematical questions surrounding these equations asks whether smooth three-dimensional solutions can remain well behaved indefinitely or whether singularities can develop in finite time.
The problem has remained unresolved for roughly 90 years and is one of the Millennium Prize Problems identified by the Clay Mathematics Institute.
OpenAI says its internal system produced a mathematical argument showing that the relevant dynamics can develop a finite-time singularity. The company published a detailed write-up together with a formalized version of the proof in Lean, a system used for machine-checked mathematical reasoning.
However, an important distinction needs to be made. OpenAI’s publication is a claimed solution, not the same thing as the mathematical community having already independently verified and accepted the result.
That distinction is particularly important when discussing AI-generated mathematical discoveries.
The 10,000-Agent Experiment Is the Bigger Story
The most unusual part of the project was not simply the model that generated the mathematical ideas.
OpenAI describes a system in which groups of AI agents were assigned different versions and approaches to the problem. The agents could explore ideas independently, communicate within groups, and later have useful results consolidated and passed between groups.
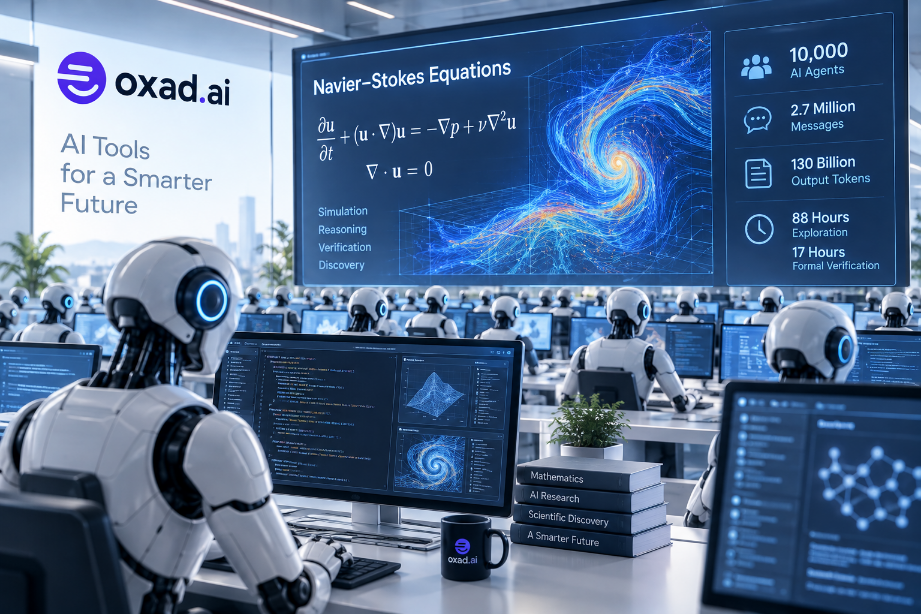
The Navier–Stokes effort involved approximately 10,000 concurrent agents. According to OpenAI, those agents generated about 2.7 million messages while working on the problem and used approximately 130 billion output tokens.
The agents reached their reported resolution after around 88 hours. A further 17 hours were used for Lean formalization and verification with GPT-6 Astra.
This is fundamentally different from the traditional image of asking an AI model a mathematical question and receiving one answer.
It is closer to building a virtual research organization.
From One AI Model to a Virtual Research Team
A conventional AI workflow might look like this:
Question → AI model → Answer
An agentic research workflow can look very different:
This architecture has an important advantage: not every agent needs to solve the entire problem.
One group can explore a mathematical construction. Another can search for counterexamples. Another can investigate a related theorem. Another can write computational experiments. Another can attempt to formalize promising results.
The system can then combine the strongest ideas.
This is similar to how large research teams work, but software agents can potentially operate in parallel at a scale that would be impossible for a human team.
Why Parallel AI Research Matters
Many difficult scientific problems are not difficult because there is only one enormous calculation to perform. They are difficult because there are enormous numbers of possible approaches.
A researcher may spend weeks or months exploring one direction only to discover that it cannot work.
Thousands of AI agents can potentially explore many directions simultaneously.
That does not guarantee success. In fact, running more agents can generate enormous amounts of low-quality information. The real challenge is therefore not simply generating more ideas.
It is determining which ideas deserve attention.
This makes coordination, evaluation, memory, and verification central components of future AI research systems.
The Role of Codex in the Research Process
Another important aspect of the experiment is the use of coding and reasoning systems to connect the different research groups.
OpenAI says Codex was used to consolidate useful insights from the different agent groups and guide subsequent research. This is significant because the system was not relying only on natural-language discussion.
AI coding systems can create computational experiments, test mathematical ideas, manipulate symbolic expressions, inspect results, and help turn abstract reasoning into executable verification.
OpenAI says the final Lean formalization and verification stage took an additional 17 hours and involved GPT-6 Astra.
This is an interesting division of labor.
The system used for the large-scale exploration was more capable than Astra, according to OpenAI. Astra was then used in a supporting role to help formalize and verify the resulting mathematics.
This suggests that future AI research systems may not rely on a single universal model.
Instead, different models could specialize in different parts of the research pipeline.
One model might be optimized for generating hypotheses. Another might specialize in coding. Another might evaluate arguments. Another might perform formal verification.
The overall system could therefore become more capable than any individual model inside it.
AI Research May Become a Multi-Agent Problem
The implications extend well beyond mathematics.
Imagine a scientific research system investigating a new material.
One group of agents could search the literature. Another could generate candidate molecular structures. Another could simulate their properties. Another could analyze experimental results. A separate group could look for contradictions and failure cases.
The same architecture could potentially be applied to physics, chemistry, biology, engineering, software development, and climate research.
The important change is that AI would no longer be used only as a research assistant.
It could become part of the research organization itself.
But More Agents Do Not Automatically Mean Better Science
It would be a mistake to interpret the Navier–Stokes experiment as proof that simply increasing the number of AI agents will solve every difficult scientific problem.
Ten thousand agents can also produce ten thousand versions of the wrong idea.
Without strong evaluation mechanisms, large-scale agent systems can amplify errors rather than eliminate them.
This is why the verification layer is so important.
Mathematical formalization, reproducible experiments, independent review, adversarial checking, and human scientific judgment remain critical.
The more autonomous the research system becomes, the more important it is to have mechanisms capable of detecting when the system has convinced itself of something that is not actually true.
The Verification Problem May Become More Important Than the Generation Problem
AI systems are becoming increasingly good at generating possibilities.
The harder problem may soon be deciding which possibilities are correct.
In scientific research, an attractive hypothesis is not enough. It needs evidence.
A mathematical proof needs to be logically valid. A physical theory needs to agree with observations. A chemical prediction needs experimental confirmation. A software solution needs to work under realistic conditions.
This means the future of AI research may depend heavily on systems that can challenge AI-generated ideas rather than simply produce more of them.
The emerging research loop
Generate hypotheses → test them → search for counterexamples → verify the strongest results → formalize what can be formalized → submit the findings to independent scrutiny.
The Controversy Around the Discovery Matters
The mathematical claim has also triggered a broader debate about how AI companies conduct research.
OpenAI says its project began after researchers heard rumors that mathematicians Tristan Buckmaster and Levent Alpöge were making progress related to major mathematical problems. The company then launched an internal effort to evaluate its own frontier system against open Millennium Prize Problems.
That timing has raised questions about scientific priority and whether AI companies can inadvertently gain an advantage from researchers who use their products while working on unpublished ideas.
OpenAI has denied directly accessing the researchers’ private work, while acknowledging that it could not completely rule out the possibility that de-identified data derived from product usage had indirectly contributed to model improvement.
The disagreement is still developing, and it is important not to present allegations as established facts.
But the broader question is legitimate: what protections should researchers have when they use AI platforms to work on unpublished discoveries?
AI Could Change Scientific Credit
Traditional scientific research has relatively clear expectations around authorship and contribution.
A researcher develops an idea, performs the work, writes the paper, and receives credit.
AI-assisted research complicates that model.
If a scientist discovers an important idea with the help of an AI model, who contributed the idea?
What happens if thousands of AI agents generate intermediate results?
Should the human researchers receive all the credit? Should the AI system be treated as a tool? What if an AI company’s infrastructure played a critical role in the discovery?
These questions are not merely philosophical. They will increasingly affect academic publishing, intellectual property, scientific collaboration, and trust in AI research platforms.
Why This Matters for Developers
The same technologies used in this research experiment are gradually appearing in software development.
AI coding agents can already inspect repositories, modify files, run tests, investigate problems, and work through multi-step engineering tasks.
Developers therefore have an early opportunity to understand the architecture behind large-scale agentic research.
Tools such as CodeRabbit demonstrate how AI can already participate in code review and software quality workflows, while developer platforms such as Context.dev focus on providing AI systems with better context for complex software tasks.
The same fundamental pattern is emerging across both fields:
Give AI context, give it tools, divide complex tasks into smaller objectives, evaluate the results, and allow useful information to flow between specialized agents.
Could Thousands of AI Agents Become the New Research Lab?
It is too early to say that AI has replaced scientific research teams.
Human researchers still define important questions, interpret results, challenge assumptions, decide what matters, and provide the scientific judgment necessary to distinguish an interesting result from a meaningful discovery.
But the economics of exploration could change dramatically.
A research team that previously had the capacity to investigate a handful of approaches may eventually be able to investigate thousands.
The limiting factor may shift from the number of people available to perform experiments toward the quality of the system used to coordinate and evaluate those experiments.
That would represent a profound change in scientific productivity.
The Cost of AI-Driven Discovery
There is another important limitation: computation.
OpenAI reports that the broader experiment across multiple mathematical problems generated around 4.9 million messages and approximately 300 billion output tokens. The Navier–Stokes effort alone accounted for around 130 billion output tokens.
That scale of computation is far beyond what most researchers can currently afford.
This creates an important question for the future: will large-scale AI research become widely accessible, or will the most powerful scientific discovery systems remain concentrated inside organizations with enormous computing resources?
If the latter happens, AI could accelerate science while simultaneously increasing the gap between well-funded research institutions and smaller laboratories.
What Comes Next?
The Navier–Stokes experiment should be viewed as an early demonstration of a much broader direction.
AI systems are moving from answering questions to organizing work.
They are beginning to divide problems, explore alternatives, write and execute code, communicate intermediate findings, and verify results through specialized systems.
The next stage could involve even more sophisticated research architectures in which different AI models specialize in different scientific roles and continuously challenge one another.
That could make AI dramatically more useful for difficult scientific problems.
It could also make verification, transparency, data protection, and scientific governance dramatically more important.
Final Takeaway
OpenAI’s Navier–Stokes experiment is important for two different reasons.
The first is mathematical: the company says its internal AI system has produced a proposed solution to a problem that has resisted a definitive resolution for decades. That claim still deserves independent mathematical scrutiny.
The second is technological, and arguably more consequential.
OpenAI demonstrated a research architecture involving thousands of AI agents working concurrently, exploring different approaches, exchanging information, using coding systems, and ultimately feeding promising results into a formal verification process.
That is a very different vision of AI from the chatbot model that dominates public perception today.
The future may not be about having one AI that knows everything.
It may be about building systems in which thousands of specialized AI agents can work together, challenge one another, and gradually transform difficult questions into testable results.
If that model continues to improve, AI may become not just a tool researchers use, but part of the infrastructure through which new scientific knowledge is discovered.
Explore AI Research and Developer Tools
Discover AI tools for coding, research, automation, and modern development workflows through the OXAD.AI directory.